GridVAD
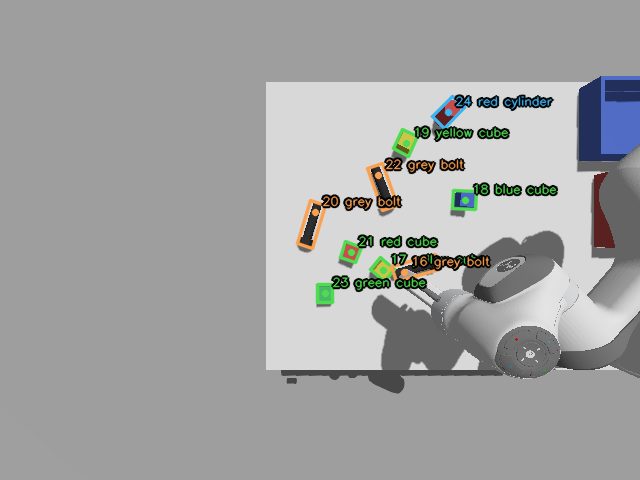
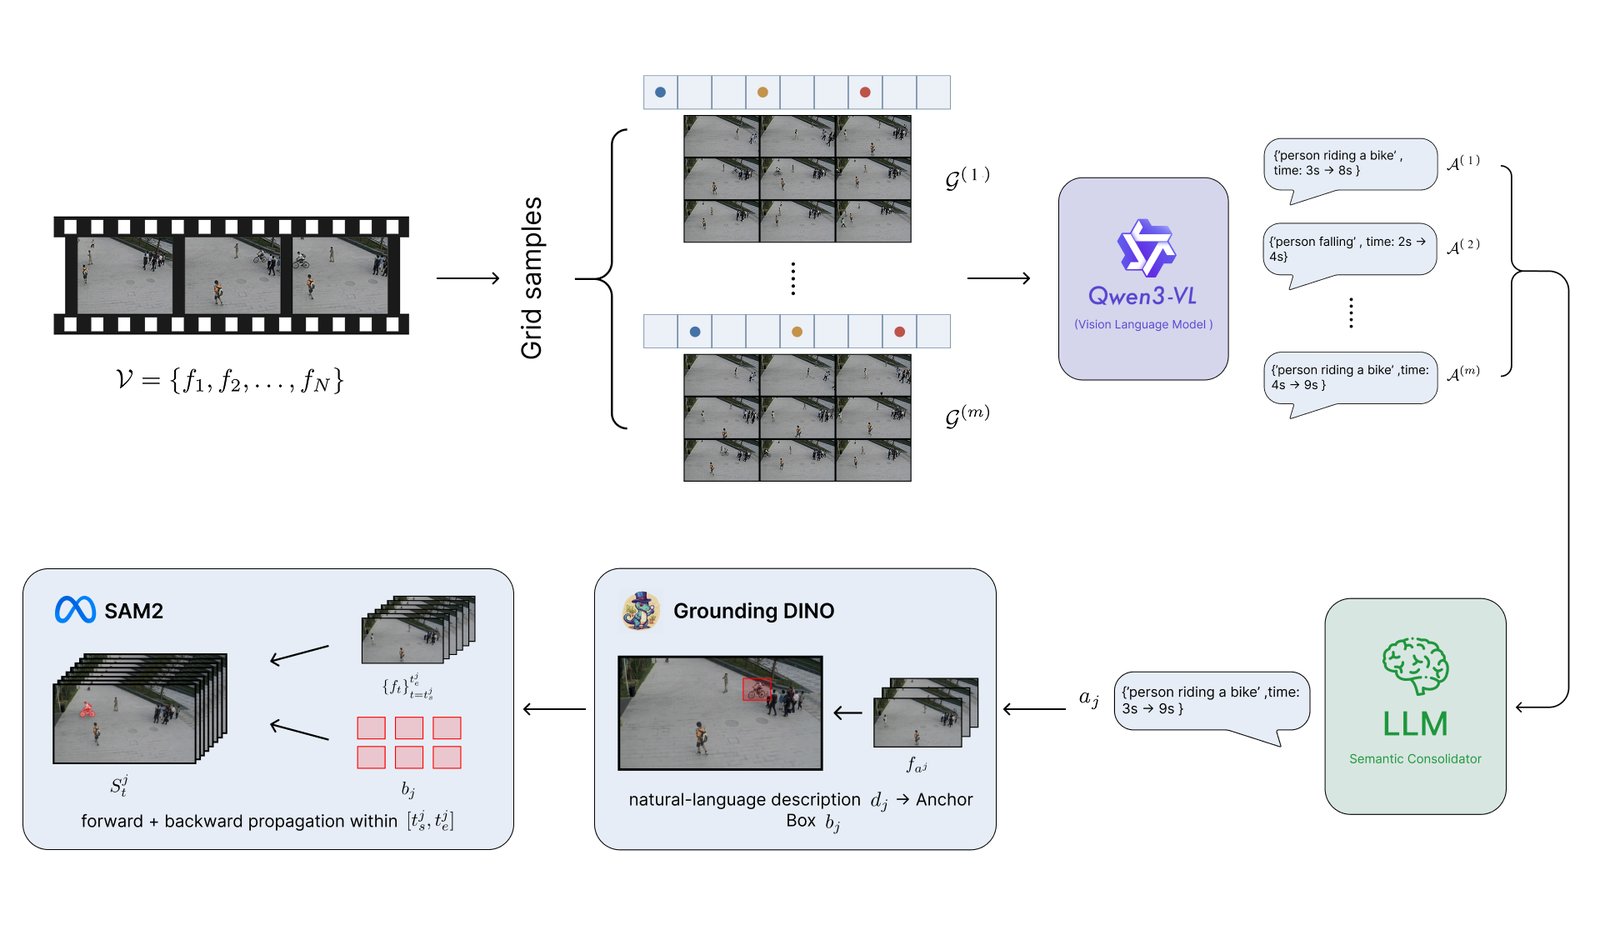
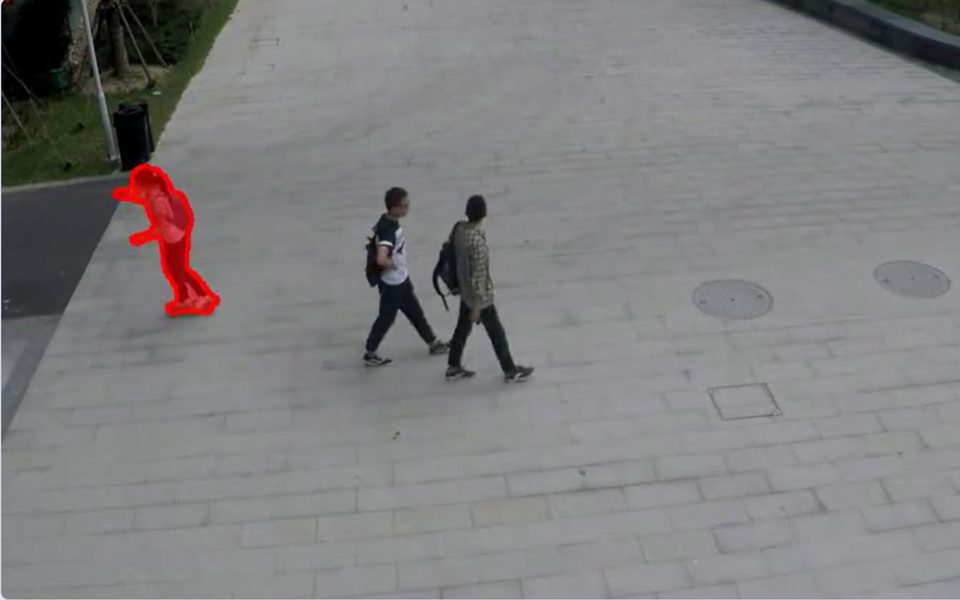
Training-free, open-set video anomaly detection. A vision-language model reads stratified frame grids and proposes anomalies in words; only proposals that recur across samplings survive; Grounding DINO and SAM 2 turn them into masks. Highest Pixel-AUROC on UCSD Ped2 among compared methods (77.59), with 2.7× fewer model calls than per-frame querying.
M. Eltahir, A. O. Ibrahim*, O. Siralkhatim*, T. Abdallah, S. Mohamed. LSVOS Workshop, ECCV 2026, Malmö. *Equal contribution.